PDFMathTranslate
使用 AI 翻译 PDF 文档,尽量保留原文档排版,便于双语阅读。
中文简介经编辑校订 · chinese / document / edit / english / japanese / korean
README / 项目原文





1. What does this do?
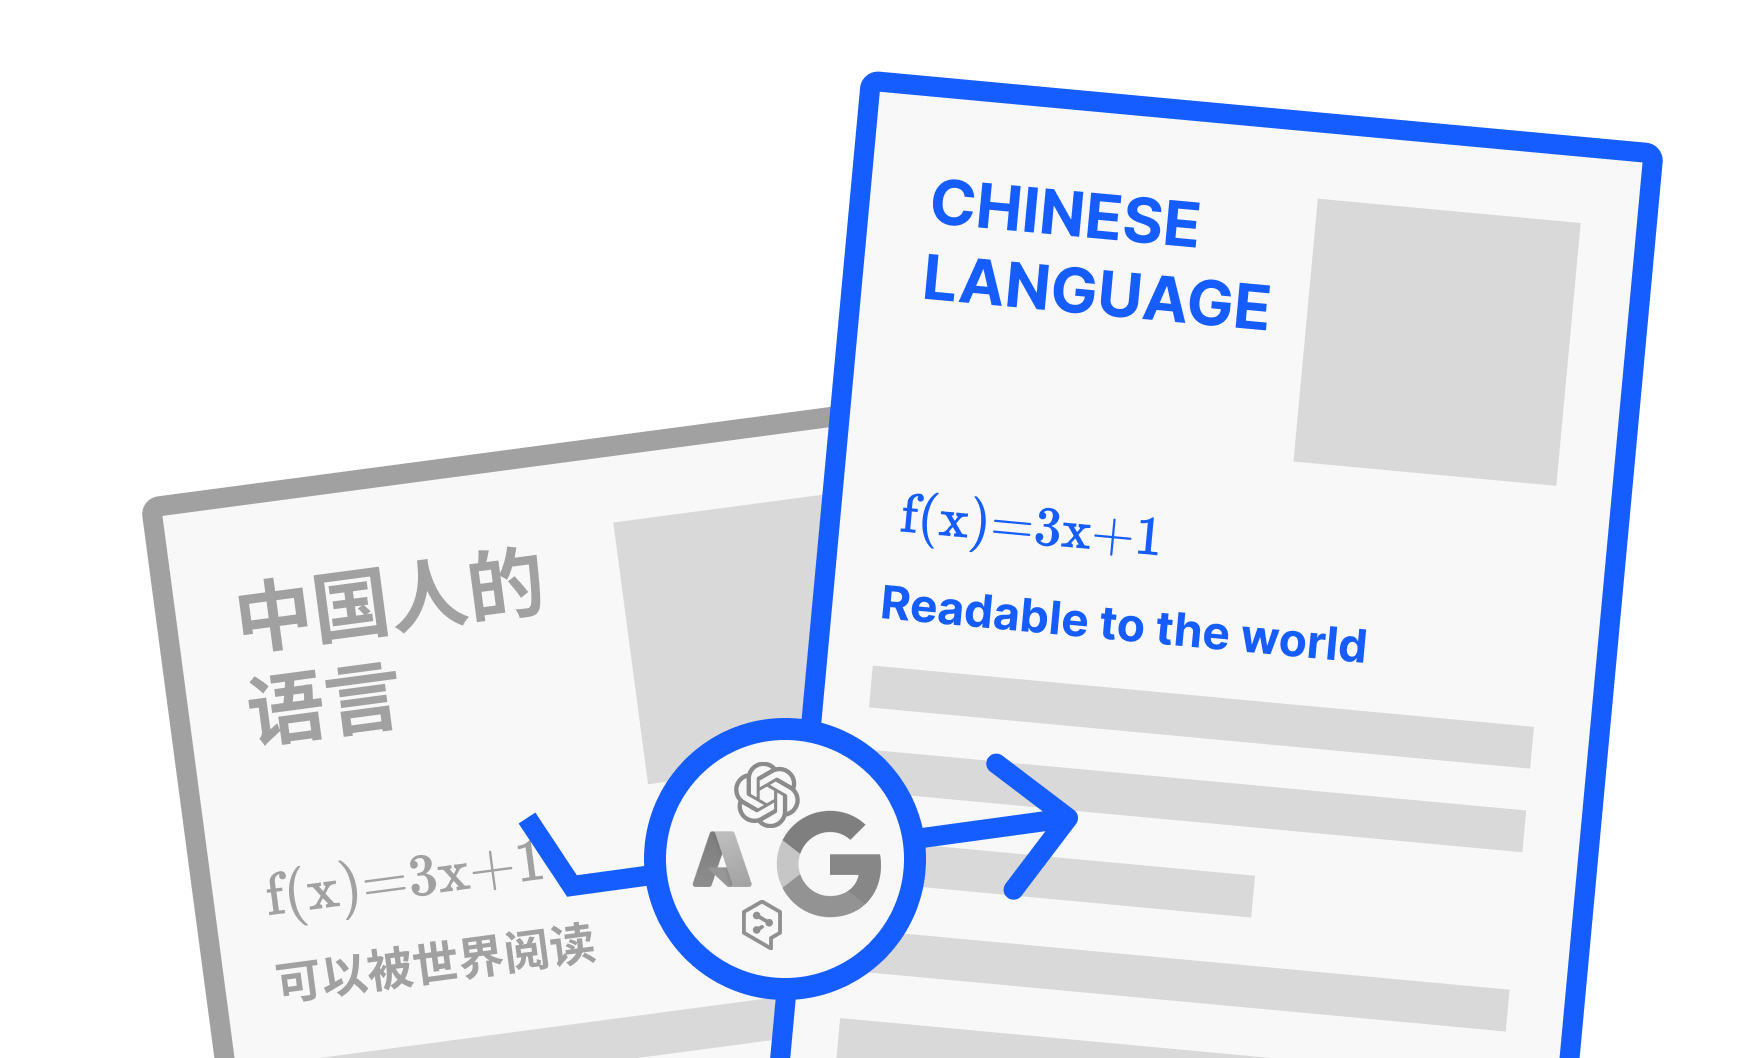
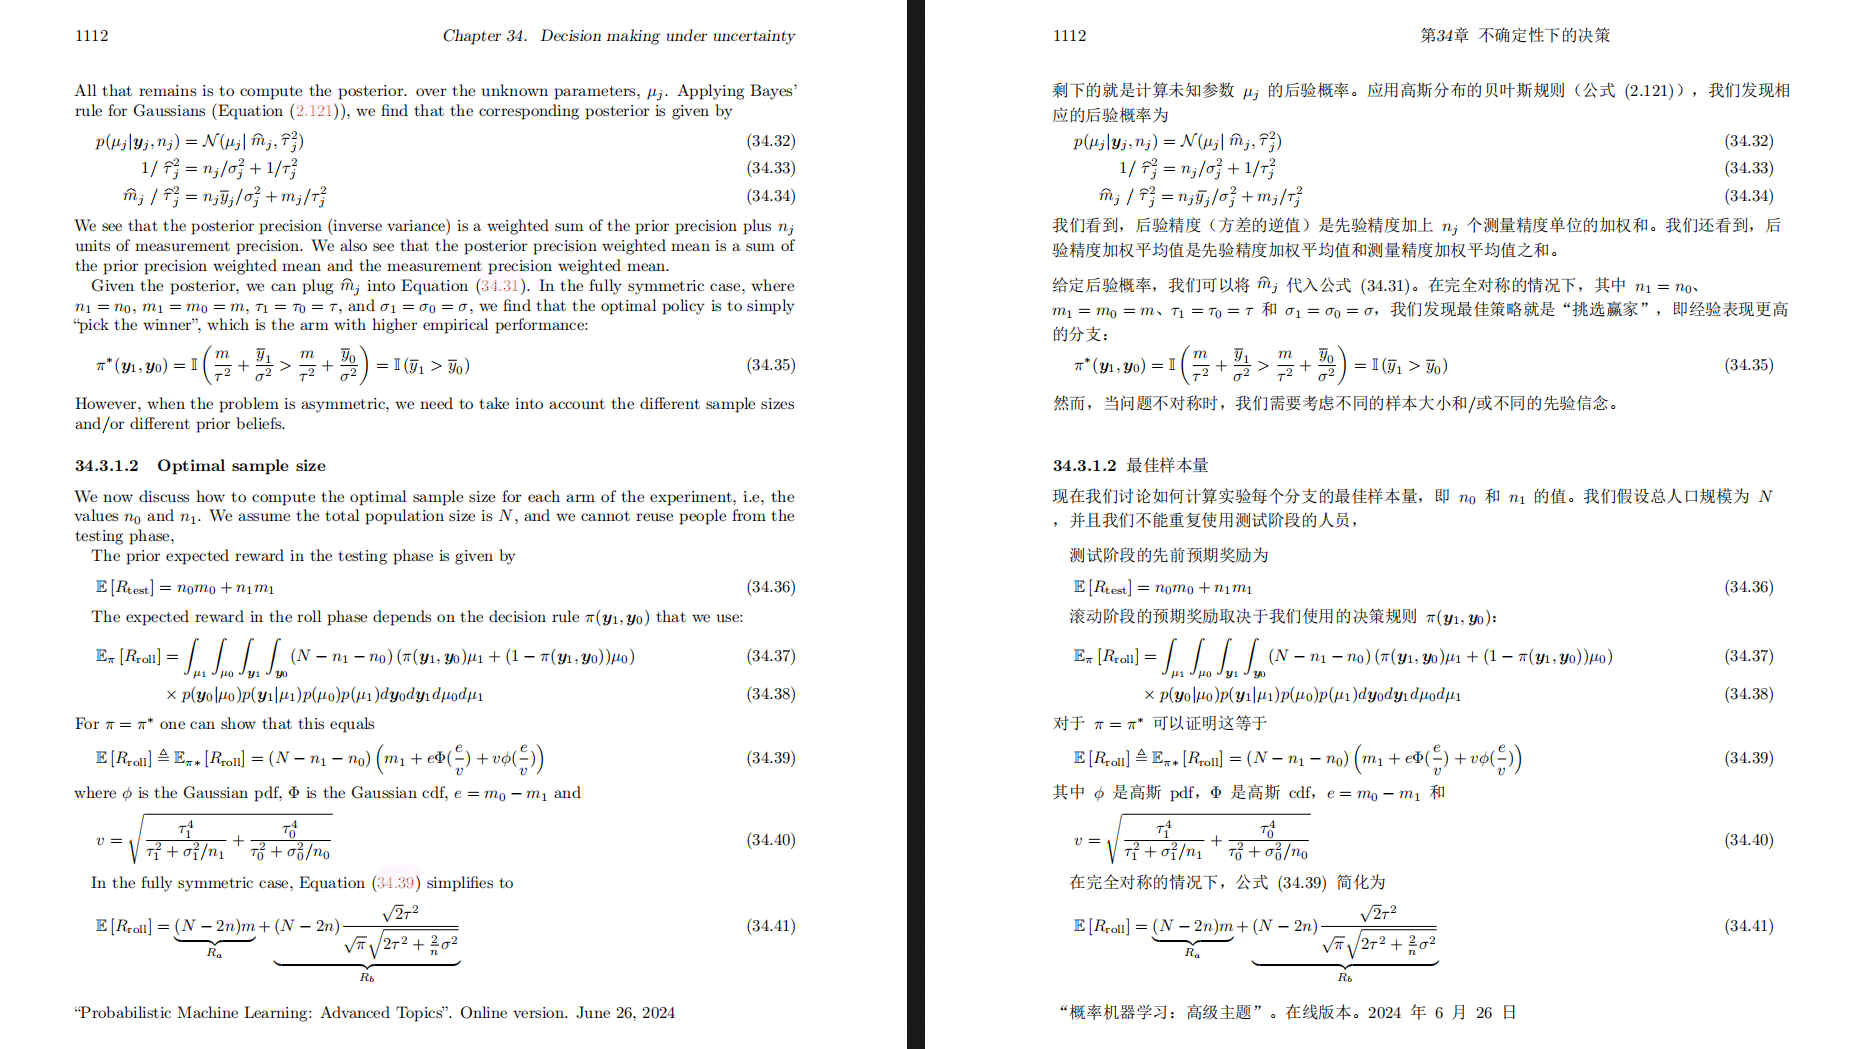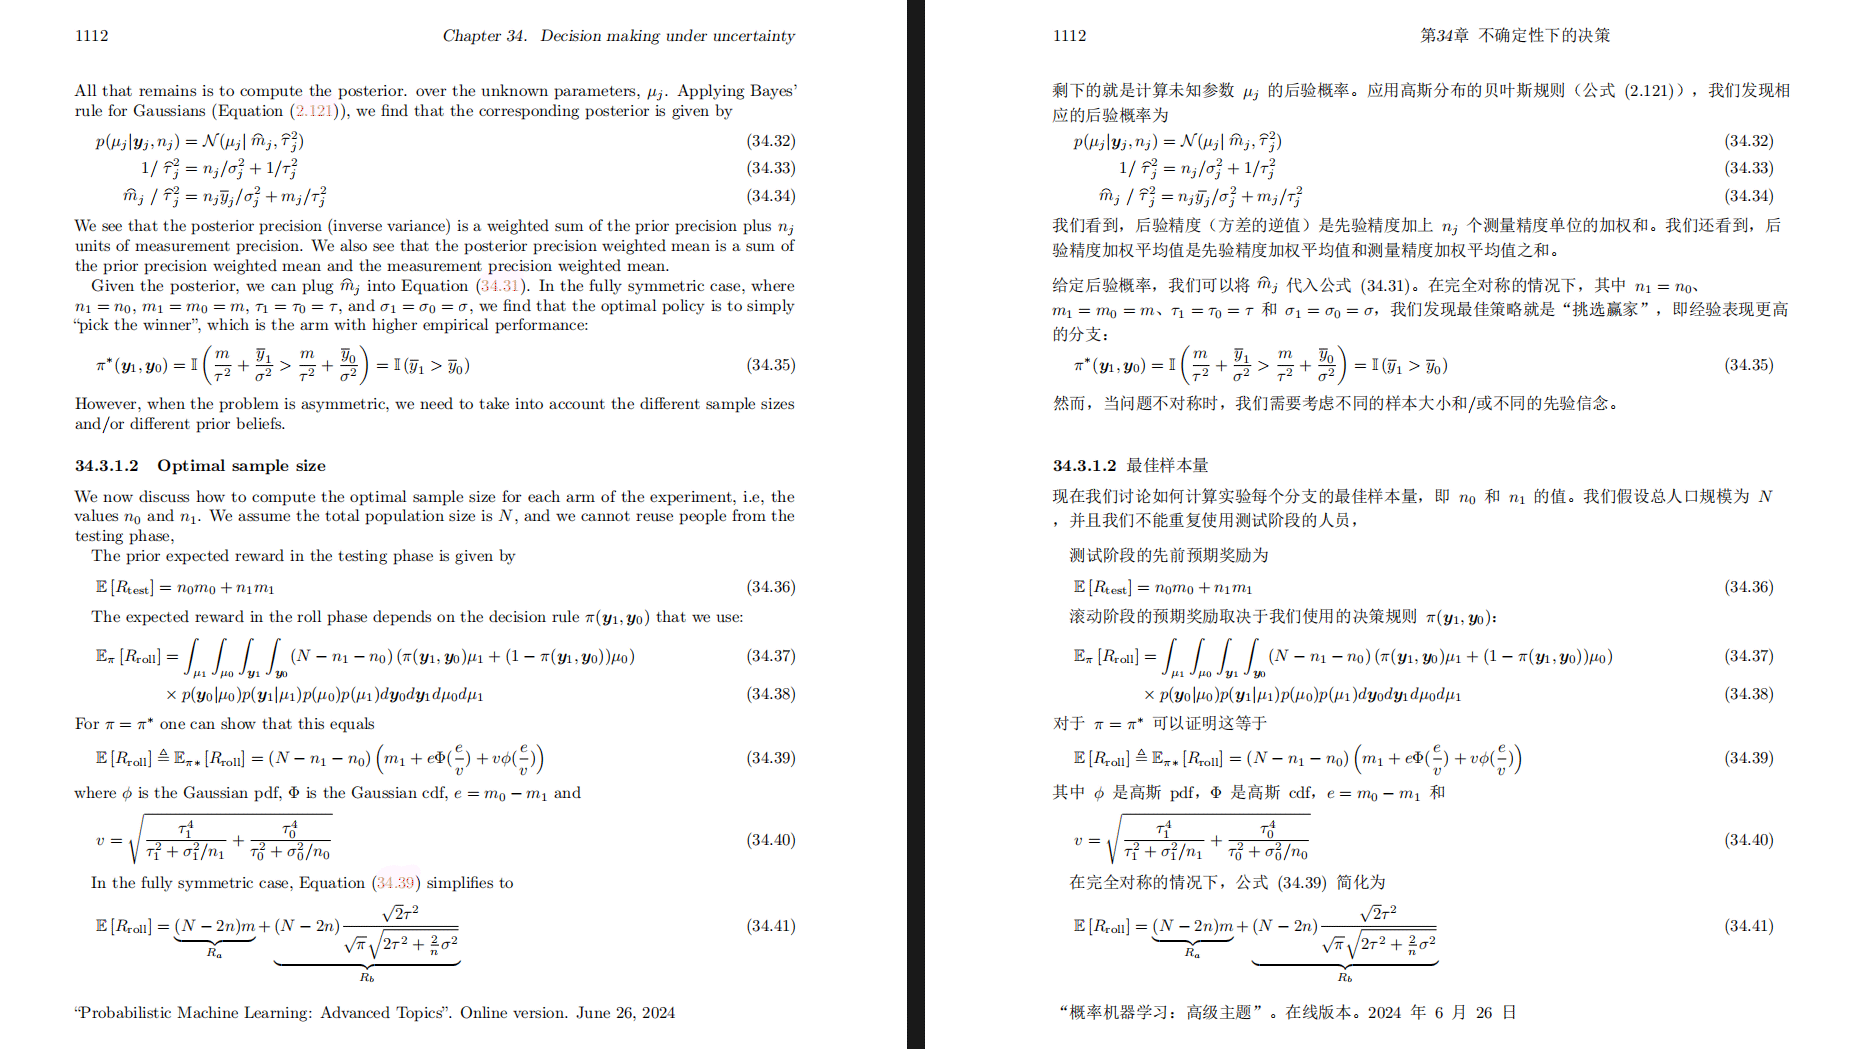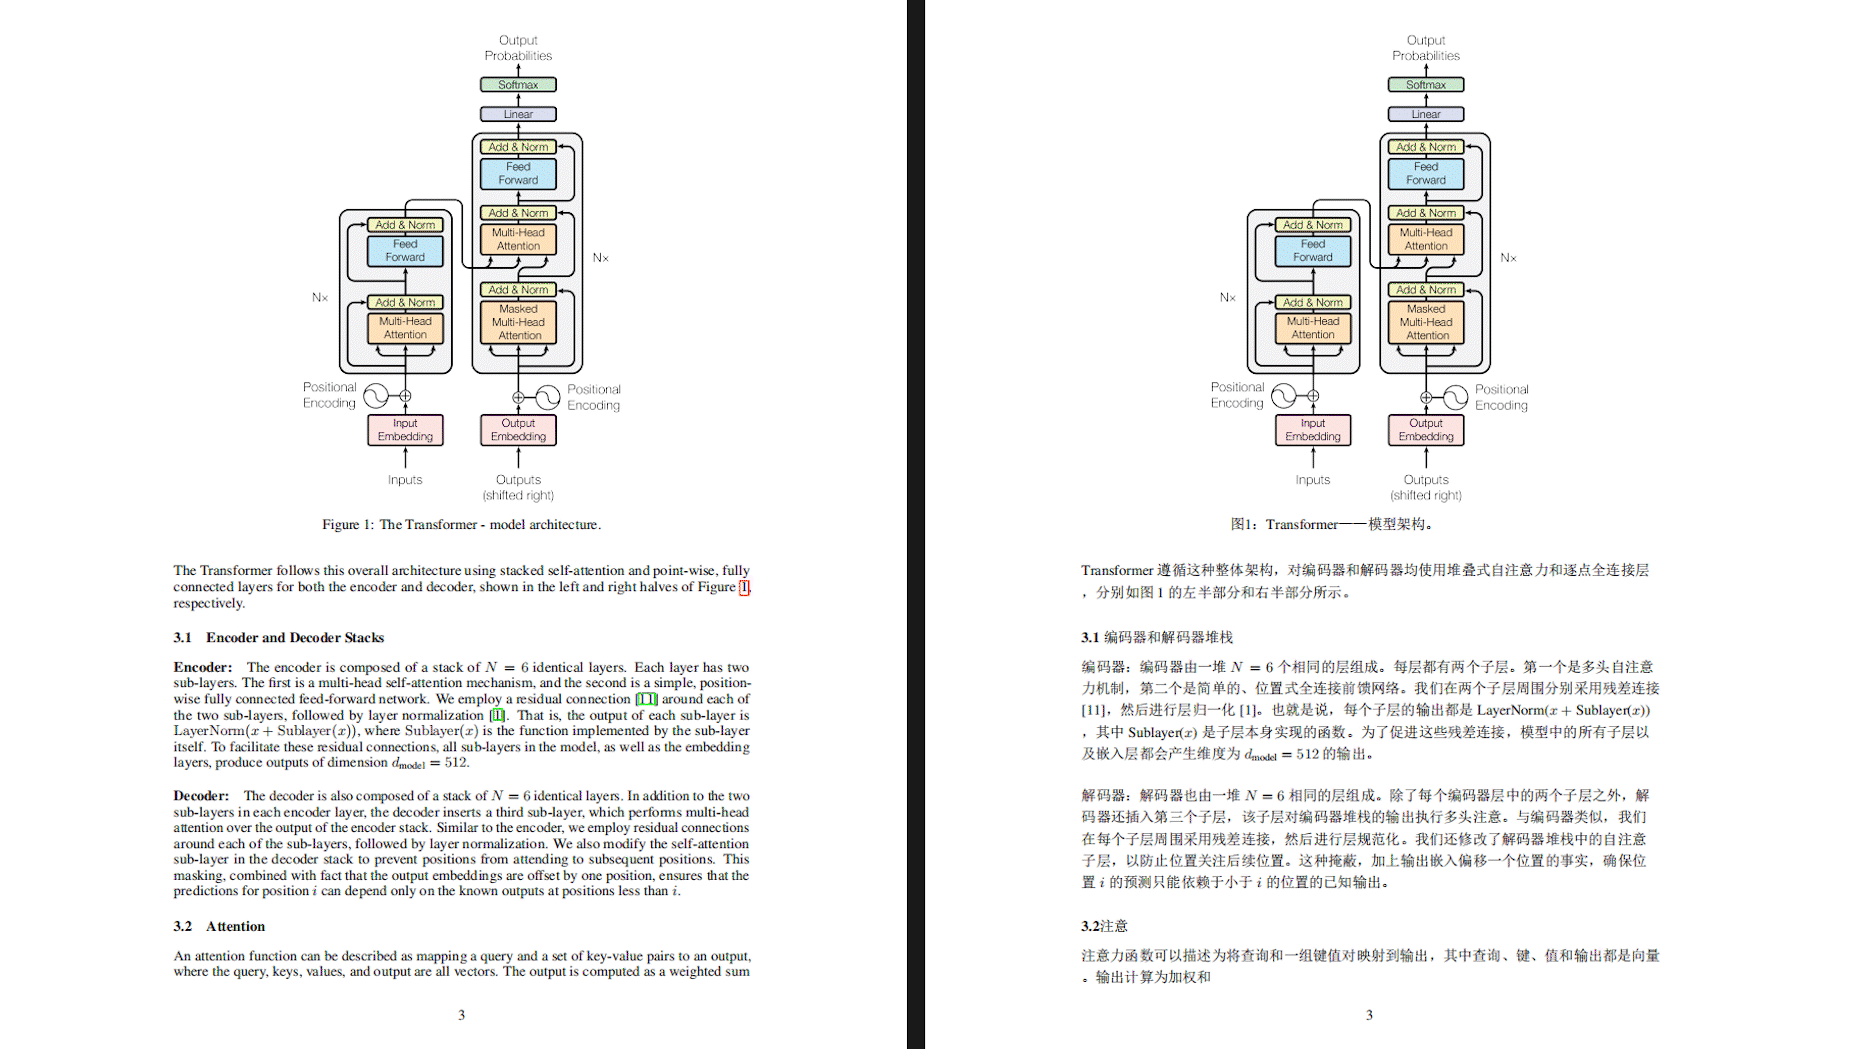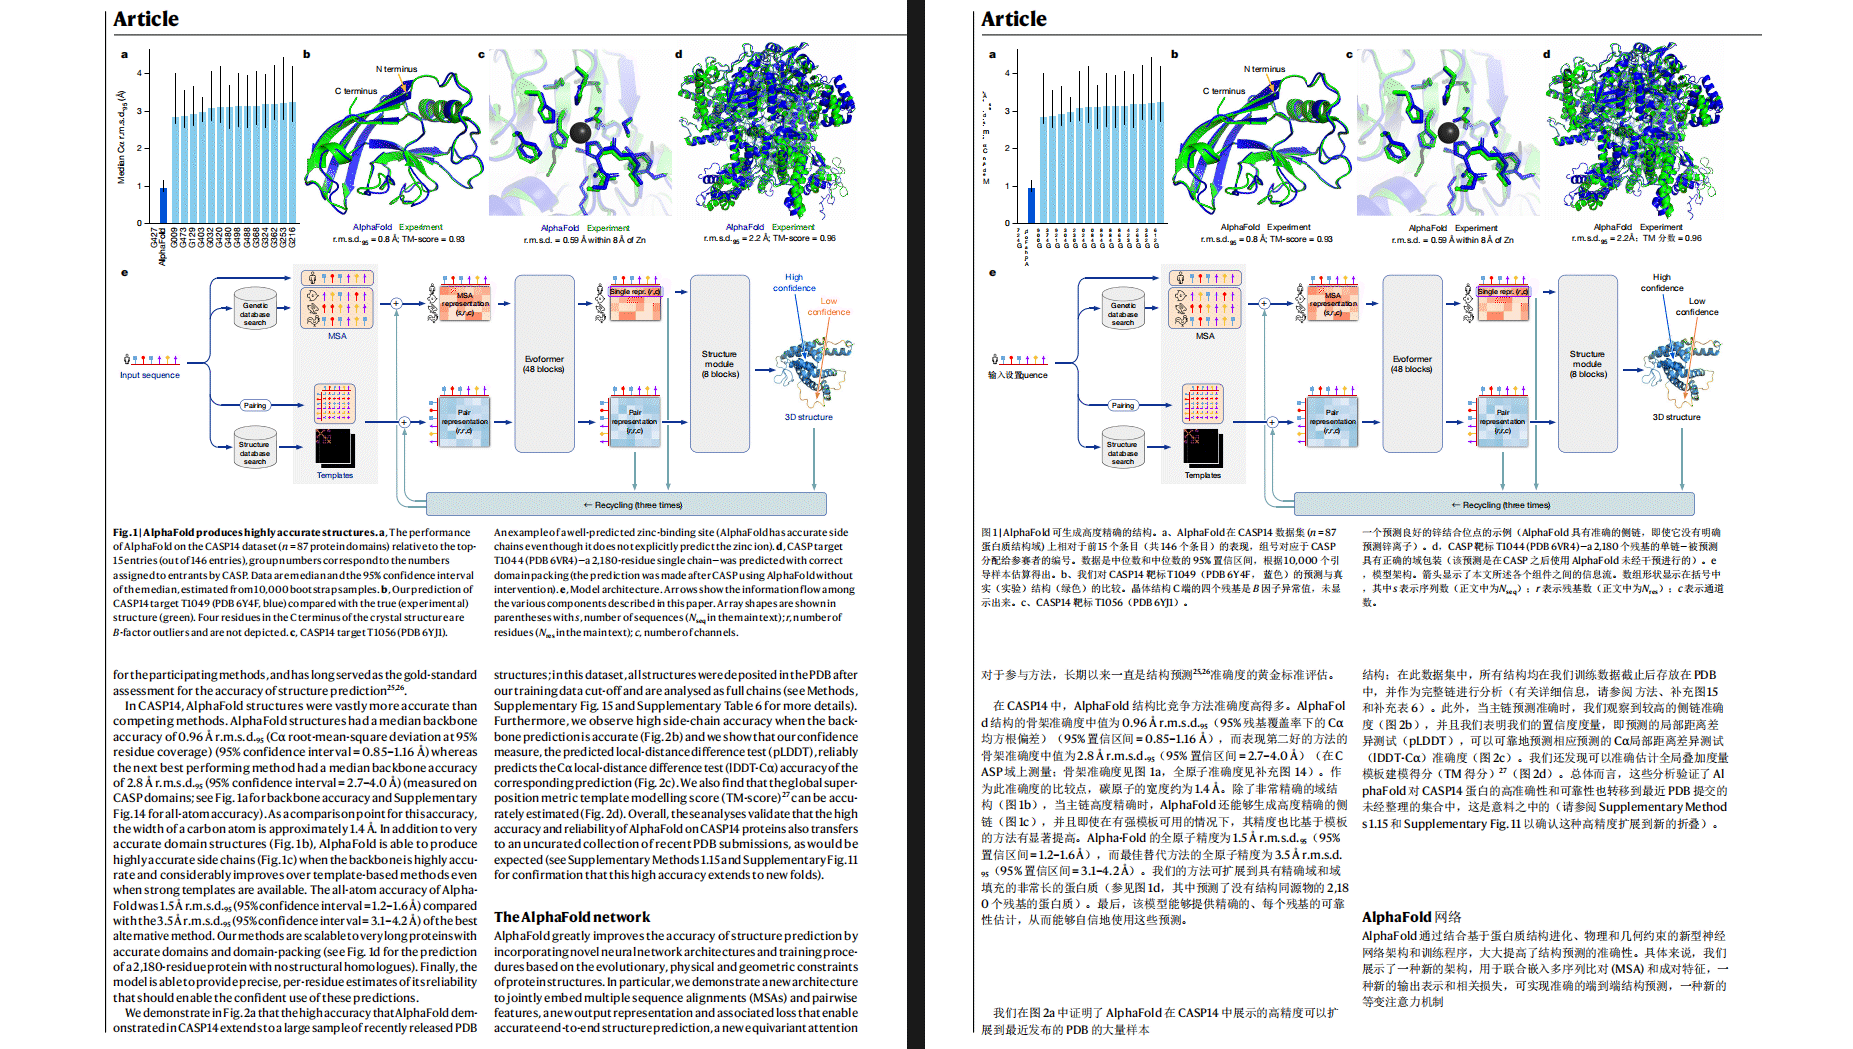
Scientific PDF document translation preserving layouts.
- 📊 Preserve formulas, charts, table of contents, and annotations.
- 🌐 Support multiple languages, and diverse translation services.
- 🤖 Provides commandline tool, interactive user interface, and Docker
2. Recent Updates
[October 3, 2026] Translated PDFs automatically add spaces between adjacent CJK and Latin letters, including accented letters, in normal and
--ultrafastmodes.[October 2, 2026] Added the
--ultrafastCLI mode for native-text PDFs. It usespdf-inspectortext positions for heuristic layout and skips ONNX layout and OCR. (by @reycn)[September 8, 2026] Experimental OCR support, with paragraph regrouping and adaptive typesetting. (by @reycn)
[March 23, 2026] Experimental support for v2.0 translation kernel using isolated environment (
--mode precise). (by @reycn)[March 22, 2026] Supporting MiniMax (PR by @octo-patch)
[March 22, 2026] Fixing OpenAI-related issues (PR by @samqin123)
[March 22, 2026] Fixing HTTP-related issues (PR by @soukouki)
[March 22, 2026] Faster model loading on mac and OONX platforms, GUI starting-up, version printing, and continuous integration.(by @reycn)
[May 9, 2025] pdf2zh 2.0 Preview Version #586: The Windows ZIP file and Docker image are now available.
[!NOTE]
2.0 Moved to a new repository under the organization: PDFMathTranslate/PDFMathTranslate-next
Version 2.0 official release has been published.
3. Use 🌟
3.1 Online Service 🌟
You can try our application out using either of the following demos:
- Public free service online without installation (recommended).
- Immersive Translate - BabelDOC Free usage quota is available; please refer to the FAQ section on the page for details. (recommended)
- Demo hosted on HuggingFace
- Demo hosted on ModelScope without installation.
Note that the computing resources of the demo are limited, so please avoid abusing them.
3.2 Local Installation
For different use cases, we provide distinct methods to use our program:
3.2.1 Python: Install using uv
Python installed (3.11 <= version <= 3.12)
Install our package:
pip install uv
uv tool install --python 3.12 pdf2zh
Execute translation, files generated in current working directory:
pdf2zh document.pdf
3.2.2 Python: Install using pip
Python installed (3.11 <= version <= 3.12)
Install our package:
pip install pdf2zhExecute translation, files generated in current working directory:
pdf2zh document.pdf
3.3.3 Python: Graphic user interface
Python installed (3.11 <= version <= 3.12)
Install our package:
pip install pdf2zh
Start using in browser:
pdf2zh -iIf your browser has not been started automatically, goto
http://localhost:7860/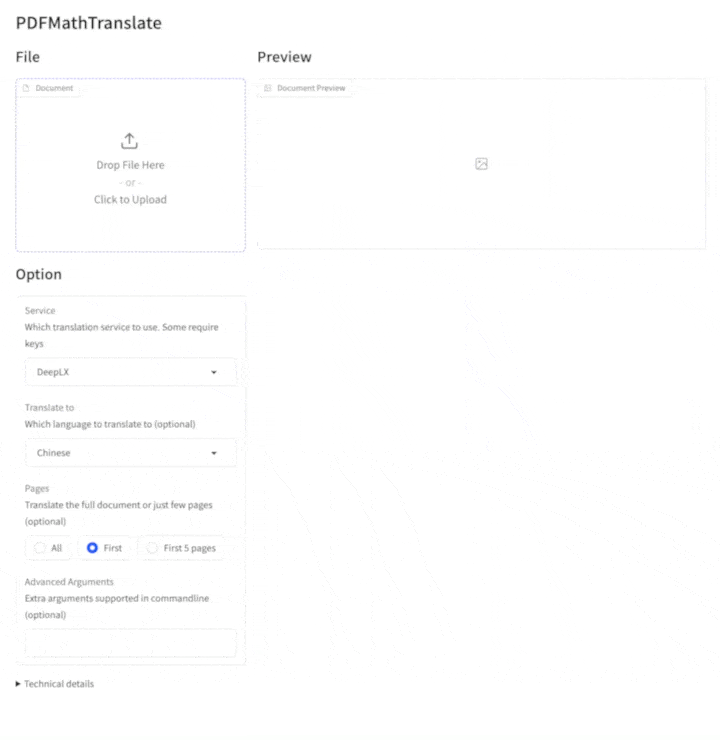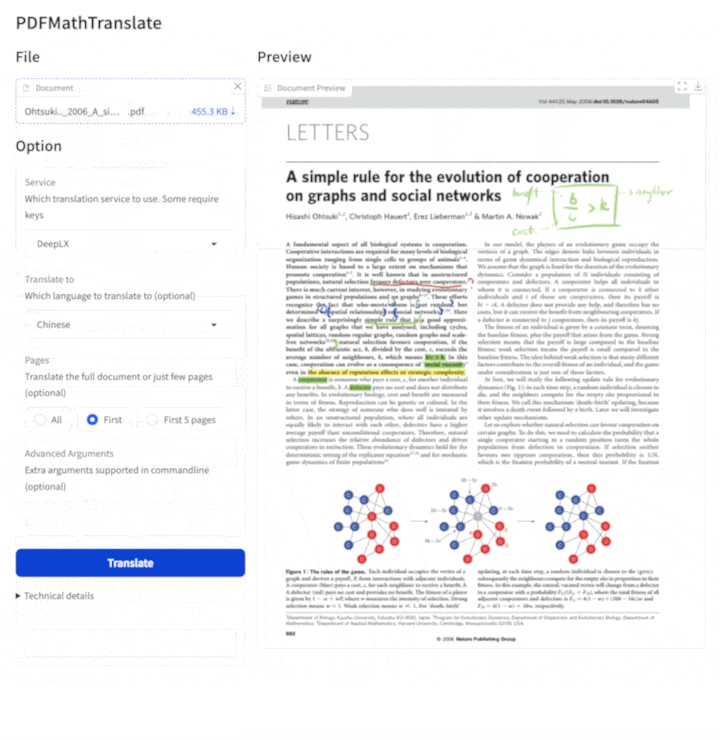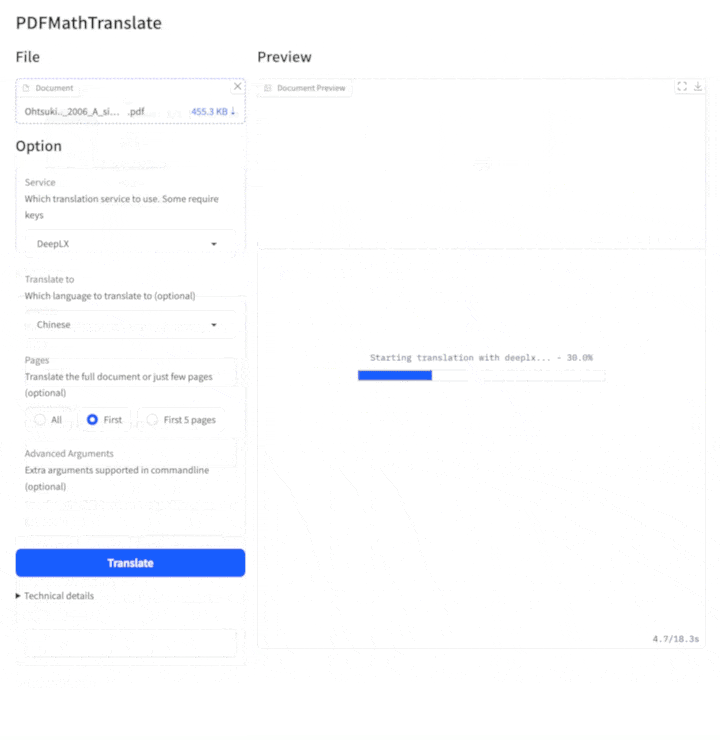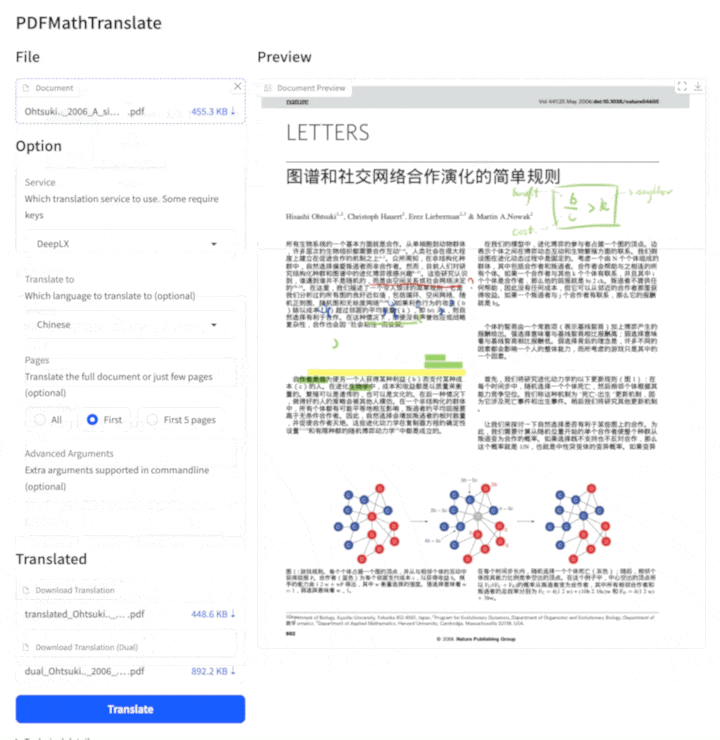
See documentation for GUI for more details.
3.2.4 Application: On Windows
Download pdf2zh-version-win64.zip from release page
Unzip and double-click
pdf2zh.exeto run.
[!TIP]
- If you're using Windows and cannot open the file after downloading, please install vc_redist.x64.exe and try again.
3.2.5 Reference manager: Zotero Plugin
See Zotero PDF2zh for more details.
3.2.6 Docker: Containerized Deployment
Pull and run:
docker pull byaidu/pdf2zh
docker run -d -p 7860:7860 byaidu/pdf2zh
Open in browser:
http://localhost:7860/
For docker deployment on cloud service:


[!TIP]
- If you cannot access Docker Hub, please try the image on GitHub Container Registry.
docker pull ghcr.io/byaidu/pdfmathtranslate
docker run -d -p 7860:7860 ghcr.io/byaidu/pdfmathtranslate
3.2.* Solutions for network issues in installation
Users in specific regions may encounter network difficulties when loading the AI model. The current program relies on the AI model (wybxc/DocLayout-YOLO-DocStructBench-onnx), and some users are unable to download it due to these network issues.
To address issues with downloading this model, use the following environment variable as a workaround:
set HF_ENDPOINT=https://hf-mirror.com
For PowerShell user:
$env:HF_ENDPOINT = https://hf-mirror.com
If the solution does not work to you / you encountered other issues, please refer to Frequently Asked Questions.
4. Technical Details
Experimental automatic OCR (fast mode)
Fast mode automatically runs local OCR on selected image-only pages before
translation. Native text, existing OCR layers, and blank pages are skipped;
the original pages in dual output remain unchanged. Install with
pip install 'pdf2zh[ocr]' (or pip install -e '.[ocr]' from this checkout).
The first scanned page downloads the requested language data from Tesseract's
tessdata_fast 4.1.0 release into ~/.cache/pdf2zh/tessdata/4.1.0; subsequent
runs reuse it offline. Native-text PDFs do not trigger downloads.
OCR uses the input language; PDF2ZH_OCR_LANGUAGE=eng+deu overrides it with
Tesseract language codes. Set TESSDATA_PREFIX to use your own data without
automatic downloads.
PyMuPDF supplies the OCR engine; the optional extra adds Pooch for cached downloads. No separate Tesseract executable is required. OCR words are regrouped into paragraphs within detected layout regions before translation, with wrapped lines and soft hyphens joined. Translated paragraphs start at the median source font size and shrink to fit their original boxes; detected figures, tables, and standalone formulas remain untouched. The initial implementation targets white-background scans: partial scans on pages that already contain text are skipped, and handwritten text or inline equations may be recognized incorrectly. Precise mode is unchanged.
Ultrafast mode
Install the optional pdf-inspector>=1.25.2,<2 dependency with
pip install 'pdf2zh[ultrafast]', then run:
pdf2zh example.pdf --ultrafast
--ultrafast uses native PDF text positions from pdf-inspector for heuristic
layout. It skips ONNX layout and OCR; pages without native text are preserved
without OCR. Its heuristic text grouping retains the usual font and character
formula safeguards. It is best suited to PDFs that already contain native text;
use normal mode for complex tables or formulas. It is available only in fast
CLI mode and cannot be combined with --mode precise, --babeldoc, server or
GUI modes, or --onnx. It automatically skips font subsetting, so its output
PDFs are larger, while still using BabelDOC font assets as needed. With
--ignore-cache, it bypasses both translation-cache reads and writes; normal
mode keeps its existing --ignore-cache behavior. Ultrafast uses a shared
whole-document paragraph worker pool with 16 workers by default and submits
individual paragraph requests; -t overrides this value, while normal mode
keeps its default of 4. [ultrafast perf] INFO logs report stage and per-page
timings. page_scan is the paragraph-submission scan; translation is the
elapsed wait for the whole-document pool to drain, including API retries, so
it is not a sum of per-page waits. paragraph_parse covers both passes,
typesetting runs after translation completes, and layout_extract is
reported separately before font setup. page_processing includes nested
layout_mask, paragraph_parse, translation, and typesetting timings, so
do not sum the nested values again. This path does not import ONNX or OpenCV.
4.1 Advanced options
Execute the translation command in the command line to generate the translated document example-mono.pdf and the bilingual document example-dual.pdf in the current working directory. Use Google as the default translation service. More support translation services can find HERE.
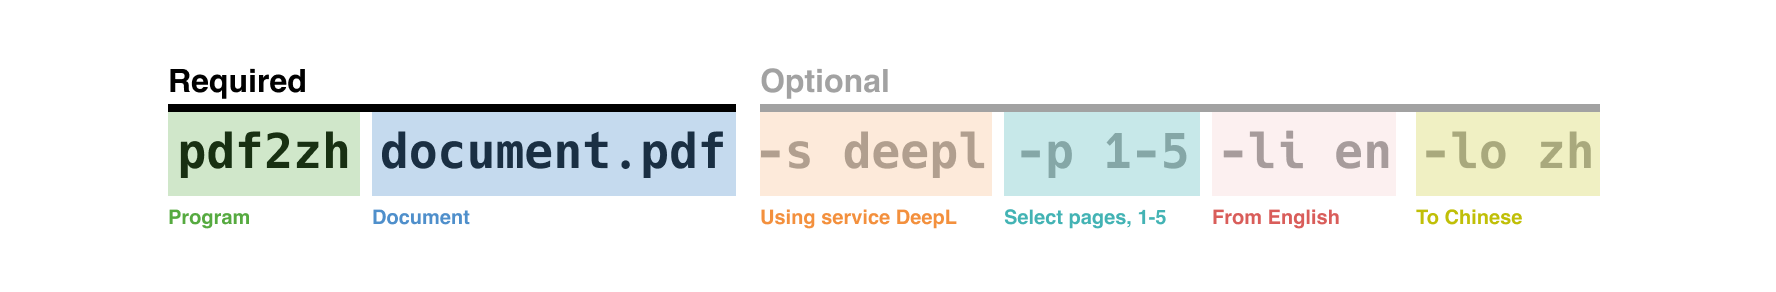
In the following table, we list all advanced options for reference:
| Option | Function | Example |
|---|---|---|
| files | Local files | pdf2zh ~/local.pdf |
| links | Online files | pdf2zh http://arxiv.org/paper.pdf |
-i |
Enter GUI | pdf2zh -i |
-p |
Partial document translation | pdf2zh example.pdf -p 1 |
-li |
Source language | pdf2zh example.pdf -li en |
-lo |
Target language | pdf2zh example.pdf -lo zh |
-s |
Translation service | pdf2zh example.pdf -s deepl |
-t |
Multi-threads | pdf2zh example.pdf -t 1 |
-o |
Output dir | pdf2zh example.pdf -o output |
-f, -c |
Exceptions | pdf2zh example.pdf -f "(MS.*)" |
-cp |
Compatibility Mode | pdf2zh example.pdf --compatible |
--ultrafast |
Use native PDF text positions for heuristic layout; skip ONNX layout and OCR | pdf2zh example.pdf --ultrafast |
--skip-subset-fonts |
Skip font subset | pdf2zh example.pdf --skip-subset-fonts |
--ignore-cache |
Ignore translate cache | pdf2zh example.pdf --ignore-cache |
--share |
Public link | pdf2zh -i --share |
--authorized |
Authorization | pdf2zh -i --authorized users.txt [auth.html] |
--prompt |
Custom Prompt | pdf2zh --prompt [prompt.txt] |
--onnx |
[Use Custom DocLayout-YOLO ONNX model] | pdf2zh --onnx [onnx/model/path] |
--serverport |
[Use Custom WebUI port] | pdf2zh --serverport 7860 |
--dir |
[batch translate] | pdf2zh --dir /path/to/translate/ |
--config |
configuration file | pdf2zh --config /path/to/config/config.json |
--serverport |
[custom gradio server port] | pdf2zh --serverport 7860 |
--mode |
Translation mode: fast (default, v1) or precise (v2, experimental, requires pdf2zh_next submodule) |
pdf2zh --mode precise example.pdf |
--babeldoc |
Use Experimental backend BabelDOC to translate | pdf2zh --babeldoc -s openai example.pdf |
--mcp |
Enable MCP STDIO mode | pdf2zh --mcp |
--sse |
Enable MCP SSE mode | pdf2zh --mcp --sse |
For detailed explanations, please refer to our document about Advanced Usage for a full list of each option.
4.2 Downstream Development
For downstream applications, please refer to our document about [API Details](./docs/APIS.md) for further information about:- Python API, how to use the program in other Python programs
- HTTP API, how to communicate with a server with the program installed
4.3 Differences between two major forks
Byaidu/PDFMathTranslate: The present and the original project for stable release.
PDFMathTranslate/PDFMathTranslate-next: A fork with web-ui and additional features. This fork handles a large number of marginal cases, improves PDF compatibility, and optimizes cross-column and cross-page semantic consistency, dynamic scaling, and dynamic scaling consistency, among many other translation quality improvements. However, this fork is intended solely for development and does not address compatibility issues and is not designed for community-contributions.
5. Project Information
5.1 Citation
This work has been accepted by the Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing: System Demonstrations (EMNLP 2025).
Citation:
@inproceedings{ouyang-etal-2025-pdfmathtranslate,
	    title = "{PDFM}ath{T}ranslate: Scientific Document Translation Preserving Layouts",
	    author = "Ouyang, Rongxin  and
	      Chu, Chang  and
	      Xin, Zhikuang  and
	      Ma, Xiangyao",
	    editor = {Habernal, Ivan  and
	      Schulam, Peter  and
	      Tiedemann, J{\"o}rg},
	    booktitle = "Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing: System Demonstrations",
	    month = nov,
	    year = "2025",
	    address = "Suzhou, China",
	    publisher = "Association for Computational Linguistics",
	    url = "https://aclanthology.org/2025.emnlp-demos.71/",
	    pages = "918--924",
	    ISBN = "979-8-89176-334-0",
	    abstract = "Language barriers in scientific documents hinder the diffusion and development of science and technologies. However, prior efforts in translating such documents largely overlooked the information in layouts. To bridge the gap, we introduce PDFMathTranslate, the world{'}s first open-source software for translating scientific documents while preserving layouts. Leveraging the most recent advances in large language models and precise layout detection, we contribute to the community with key improvements in precision, flexibility, and efficiency. The work is open-sourced at https://github.com/byaidu/pdfmathtranslate with more than 222k downloads."
	}
5.2 Acknowledgement
Immersive Translation sponsors monthly Pro membership redemption codes for active contributors to this project, see details at: CONTRIBUTOR_REWARD.md
New backend: BabelDOC
Document merging: PyMuPDF
Document parsing: Pdfminer.six
Document extraction: MinerU
Document Preview: Gradio PDF
Multi-threaded translation: MathTranslate
Layout parsing: DocLayout-YOLO
Document standard: PDF Explained, PDF Cheat Sheets
Multilingual Font: Go Noto Universal
5.3 Contributors


For details on how to contribute, please consult the Contribution Guide.
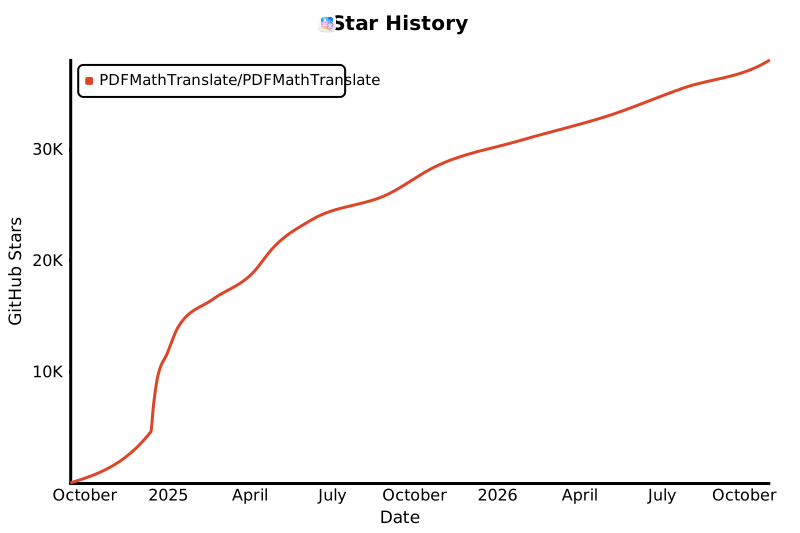
5.4 Star History
科学 PDF 文档翻译及双语对照工具
欢迎在 GitHub Issues 或 Telegram 用户群
有关如何贡献的详细信息,请查阅 贡献指南
更新
[2026年10月2日] 新增命令行
--ultrafast模式:使用pdf-inspector提供的 PDF 原生文本位置进行启发式布局,跳过 ONNX 布局解析和 OCR,适用于包含原生文本的 PDF。[2026年3月23日] 实验性支持 v2.0 翻译内核,使用隔离环境运行(
--mode precise)。(由@reycn 提交)[2026年3月22日] 支持 MiniMax(由@octo-patch 提交的PR)
[2026年3月22日] 修复与 OpenAI 相关的问题(由@samqin123 提交的PR)
[2026年3月22日] 修复与 HTTP 相关的问题(由@soukouki 提交的PR)
[2026年3月22日] 在 mac 和 OONX 平台上加快模型加载速度,GUI 启动,版本打印和持续集成。(由@reycn 提交)
[2025 年 2 月 22 日] 更好的发布 CI 和精心打包的 windows-amd64 exe (由 @awwaawwa 提供)
[2024 年 12 月 24 日] 翻译器现在支持在 Xinference 上使用本地模型 (由 @imClumsyPanda 提供)
预览
在线演示 🌟
在线服务 🌟
您可以通过以下演示尝试我们的应用程序:
- 公共免费服务 在线使用,无需安装 (推荐)。
- 沉浸式翻译 - BabelDOC 每月免费 1000 页 (推荐)
- 在 HuggingFace 上托管的演示
- 在 ModelScope 上托管的演示 无需安装。
请注意演示的计算资源有限,请避免滥用它们。
安装和使用
方法
针对不同的使用案例,我们提供不同的方法来使用我们的程序:
1. UV 安装
安装 Python (3.11 <= 版本 <= 3.12)
安装我们的包:
pip install uv
uv tool install --python 3.12 pdf2zh
执行翻译,文件生成在 当前工作目录:
pdf2zh document.pdf
2. Windows exe
从 发布页面 下载 pdf2zh-version-win64.zip
解压缩并双击
pdf2zh.exe运行。
3. 图形用户界面
1. 安装 Python (3.11 <= 版本 <= 3.12) 2. 安装我们的包:pip install pdf2zh
在浏览器中开始使用:
pdf2zh -i如果您的浏览器没有自动启动,请访问
http://localhost:7860/
有关更多详细信息,请参阅 GUI 文档。
4. Docker
拉取并运行:
docker pull byaidu/pdf2zh
docker run -d -p 7860:7860 byaidu/pdf2zh
在浏览器中打开:
http://localhost:7860/
对于云服务上的 docker 部署:
5. Zotero 插件
有关更多细节,请参见 Zotero PDF2zh。
6. 命令行
已安装 Python(3.11 <= 版本 <= 3.12)
安装我们的包:
pip install pdf2zh执行翻译,文件生成在 当前工作目录:
pdf2zh document.pdf
[!TIP]
如果你使用 Windows 并在下载后无法打开文件,请安装 vc_redist.x64.exe 并重试。
如果你无法访问 Docker Hub,请尝试在 GitHub 容器注册中心 上使用该镜像。
docker pull ghcr.io/byaidu/pdfmathtranslate
docker run -d -p 7860:7860 ghcr.io/byaidu/pdfmathtranslate
无法安装?
当前程序在工作前需要一个 AI 模型 (wybxc/DocLayout-YOLO-DocStructBench-onnx),一些用户由于网络问题无法下载。如果你在下载此模型时遇到问题,我们提供以下环境变量的解决方法:
set HF_ENDPOINT=https://hf-mirror.com
对于 PowerShell 用户:
$env:HF_ENDPOINT = https://hf-mirror.com
如果此解决方案对您无效或您遇到其他问题,请参阅 常见问题解答。
高级选项
在命令行中执行翻译命令,在当前工作目录下生成译文文档 example-mono.pdf 和双语对照文档 example-dual.pdf,默认使用 Google 翻译服务,更多支持的服务在这里)。
在下表中,我们列出了所有高级选项供参考:
| 选项 | 功能 | 示例 |
|---|---|---|
| files | 本地文件 | pdf2zh ~/local.pdf |
| links | 在线文件 | pdf2zh http://arxiv.org/paper.pdf |
-i |
进入 GUI | pdf2zh -i |
-p |
部分文档翻译 | pdf2zh example.pdf -p 1 |
-li |
源语言 | pdf2zh example.pdf -li en |
-lo |
目标语言 | pdf2zh example.pdf -lo zh |
-s |
翻译服务 | pdf2zh example.pdf -s deepl |
-t |
多线程 | pdf2zh example.pdf -t 1 |
-o |
输出目录 | pdf2zh example.pdf -o output |
-f, -c |
异常 | pdf2zh example.pdf -f "(MS.*)" |
-cp |
兼容模式 | pdf2zh example.pdf --compatible |
--ultrafast |
使用 pdf-inspector 的 PDF 原生文本位置进行启发式布局,跳过 ONNX 布局解析和 OCR(适用于包含原生文本的 PDF) |
pdf2zh example.pdf --ultrafast |
--share |
公开链接 | pdf2zh -i --share |
--authorized |
授权 | pdf2zh -i --authorized users.txt [auth.html] |
--prompt |
自定义提示 | pdf2zh --prompt [prompt.txt] |
--onnx |
[使用自定义 DocLayout-YOLO ONNX 模型] | pdf2zh --onnx [onnx/model/path] |
--serverport |
[使用自定义 WebUI 端口] | pdf2zh --serverport 7860 |
--dir |
[批量翻译] | pdf2zh --dir /path/to/translate/ |
--config |
配置文件 | pdf2zh --config /path/to/config/config.json |
--serverport |
[自定义 gradio 服务器端口] | pdf2zh --serverport 7860 |
--mode |
翻译模式:fast(默认,v1)或 precise(v2,实验性,需要 pdf2zh_next 子模块) |
pdf2zh --mode precise example.pdf |
--babeldoc |
使用实验性后端 BabelDOC 翻译 | pdf2zh --babeldoc -s openai example.pdf |
--ultrafast 需要 pdf-inspector>=1.25.2,<2 可选依赖:pip install 'pdf2zh[ultrafast]'。该模式使用 PDF 原生文本位置进行启发式布局;没有原生文本的页面会保留且不会执行 OCR。启发式文本分组仍保留常规的字体和字符公式保护规则;对于复杂表格或公式,请使用普通模式。该模式仅支持 fast 命令行模式,不能与 --mode precise、--babeldoc、服务器或 GUI 模式以及 --onnx 一起使用。它会自动跳过字体子集化,因此输出 PDF 更大,但仍会按需使用 BabelDOC 字体资源。--ultrafast --ignore-cache 会同时跳过翻译缓存的读取和写入;普通模式的 --ignore-cache 语义不变。Ultrafast 默认使用 16 个 worker 建立整篇文档共享的段落任务池,每次请求单个段落;-t 可覆盖该值,普通模式默认仍为 4。INFO 日志会自动输出 [ultrafast perf] 的分阶段和逐页耗时。page_scan 表示提交段落任务的扫描;translation 表示等待整篇文档共享任务池排空的耗时(包括 API 重试),不能通过相加逐页等待时间重建。paragraph_parse 覆盖两次解析,typesetting 在翻译完成后执行,layout_extract 会在字体设置前单独报告。page_processing 包含嵌套的 layout_mask、paragraph_parse、translation 和 typesetting 耗时,请勿将嵌套值再次相加。此路径不会导入 ONNX 或 OpenCV。
有关详细说明,请参阅我们的文档 高级用法,以获取每个选项的完整列表。
二次开发 (API)
当前的 pdf2zh API 暂时已弃用。API 将在 pdf2zh 2.0发布后重新提供。对于需要程序化访问的用户,请使用BabelDOC的 babeldoc.high_level.async_translate 函数。
API 暂时弃用意味着:相关代码暂时不会被移除,但不会提供技术支持,也不会修复 bug。
待办事项
修复页面旋转、目录、列表格式
修复旧论文中的像素公式
异步重试,除了 KeyboardInterrupt
针对西方语言的 Knuth–Plass 算法
支持非 PDF/A 文件
致谢
Immersive Translation 为此项目的活跃贡献者提供每月的专业会员兑换码,详细信息请查看:CONTRIBUTOR_REWARD.md
文档合并:PyMuPDF
文档解析:Pdfminer.six
文档提取:MinerU
文档预览:Gradio PDF
多线程翻译:MathTranslate
布局解析:DocLayout-YOLO
多语言字体:Go Noto Universal
贡献者